Humam Motion Synthesis in 3D
Introduction
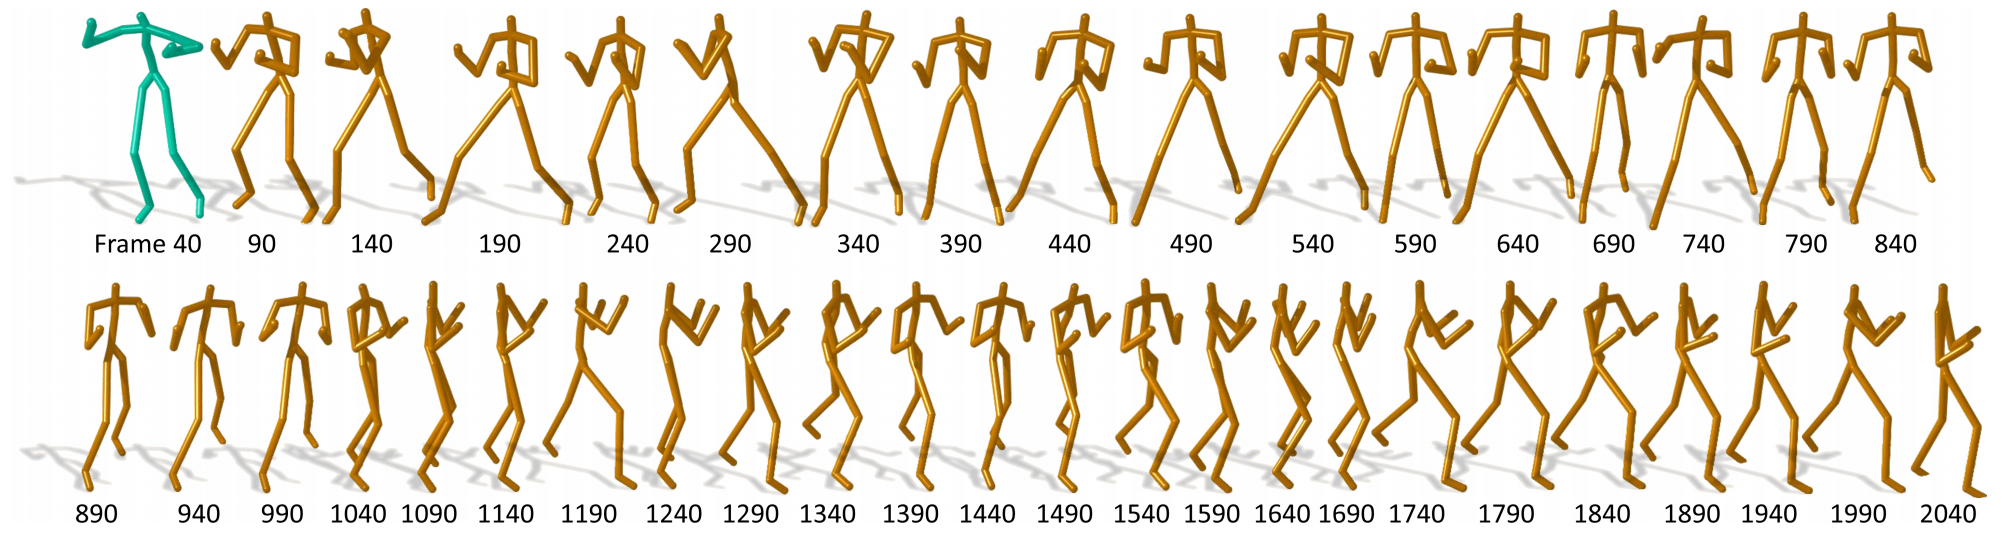
This research project focuses on the evolution of human motion synthesis and prediction, spanning over two decades of innovation from geometric constraints to cutting-edge generative AI. Our work explores how to create realistic, controllable, and expressive movement by bridging the gap between low-level kinematics and high-level behavioral intelligence. Early contributions in Inverse Kinematics and linear programming [Ho et al. VRST2005] laid the foundation for real-time pose editing, which has since evolved into sophisticated frameworks for synthesizing natural preparation behaviors [Shum et al. CAVW2014, Shum et al. CASA2013] and crowd motion control [Shen et al. CGF2018]. By integrating spatio-temporal manifold learning and long-horizon modeling [Wang et al. IEEE TVCG2021], the project addresses the inherent complexity of human dynamics, ensuring that generated motions are both physically plausible and contextually aware.
In recent years, the research has shifted toward the vanguard of generative modeling, utilizing diffusion-based architectures to redefine motion in-betweening and prediction [Fan et al. IEEE TVCG2026]. By representing motion through continuous implicit representations and quadruple diffusion convolutional networks, we develop tools that can autonomously fill gaps in movement sequences with unprecedented fluidity. This trajectory - from early skill assessment tools like SkillVis [Shum et al. MIG2016, Shen et al. C&G2017] to modern AI-driven motion forecasting [Men et al. IEEE TCSVT2021] - aims to empower animators and developers with automated systems capable of understanding, visualizing, and generating the intricate nuances of human and multi-agent interaction in virtual environments.
In recent years, the research has shifted toward the vanguard of generative modeling, utilizing diffusion-based architectures to redefine motion in-betweening and prediction [Fan et al. IEEE TVCG2026]. By representing motion through continuous implicit representations and quadruple diffusion convolutional networks, we develop tools that can autonomously fill gaps in movement sequences with unprecedented fluidity. This trajectory - from early skill assessment tools like SkillVis [Shum et al. MIG2016, Shen et al. C&G2017] to modern AI-driven motion forecasting [Men et al. IEEE TCSVT2021] - aims to empower animators and developers with automated systems capable of understanding, visualizing, and generating the intricate nuances of human and multi-agent interaction in virtual environments.
Publications
The Team